Resume and cover letter resources
Data Engineer Resume Example and Writing Guide for 2026
A strong Data Engineer resume must bridge the gap between software engineering and data science. In the current US tech market, hiring managers look for evidence of scalable architecture, cost optimization, and cloud proficiency. This guide provides a fictional professional example and strategic advice to help you showcase your technical impact and secure interviews at top firms.
Updated
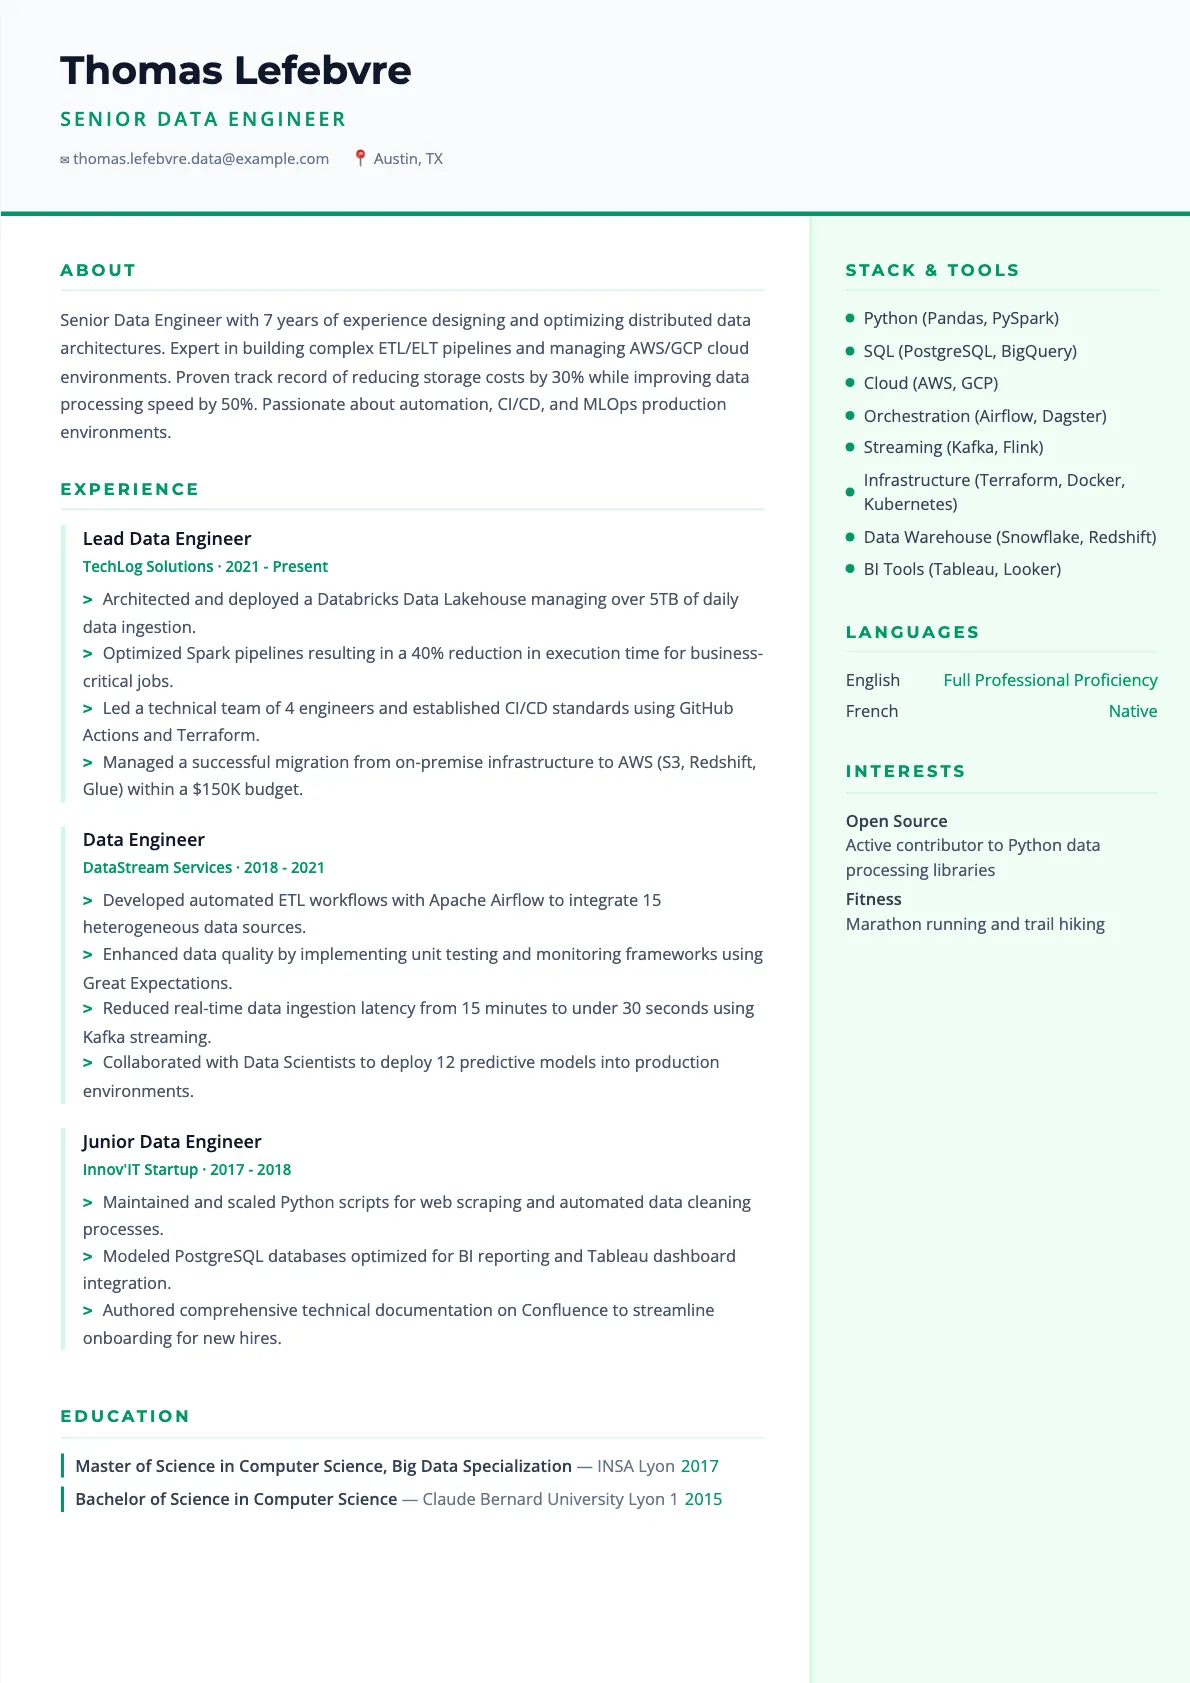
How to Quantify Technical Impact for Data Engineering Roles
Prioritize metrics related to infrastructure costs, processing latency, and data volume to validate your seniority. American tech recruiters look for engineers who treat data as a financial asset rather than just a technical challenge. Instead of stating you managed a cluster, specify that you architected a 5TB Data Lakehouse to handle 100 million daily events.
This scale provides immediate context regarding the complexity of the environments you are capable of governing.
Translate your technical optimizations into direct business value through percentage-based efficiency gains. Mentioning a 40% reduction in Spark job execution time demonstrates a deep understanding of resource allocation and query tuning. Such achievements imply a direct reduction in cloud compute billing, which is a high-priority concern for modern engineering managers.
Always connect your pipeline improvements to the end-user experience or stakeholder requirements. For example, reducing real-time ingestion latency from fifteen minutes to thirty seconds directly enables faster executive decision-making. Highlighting that you integrated fifteen heterogeneous data sources shows your ability to manage architectural variety.
These specific figures transform a list of responsibilities into a compelling narrative of professional success and technical mastery.
Essential Technical Competencies for the 2026 Job Market
Mastery of cloud-native ecosystems and distributed computing frameworks is the baseline for modern data engineering. Proficiency in AWS, GCP, or Azure must be demonstrated through specific service implementations like Redshift, BigQuery, or Snowflake. Recruiters utilize Applicant Tracking Systems to filter for these keywords, so explicit mentions of S3, Glue, or Lambda are vital.
These tools represent the core infrastructure where most enterprise-level data processing now occurs.
Software engineering rigor distinguishes top-tier engineers from those who merely write scripts. You must showcase experience with CI/CD pipelines, unit testing frameworks like Great Expectations, and Infrastructure as Code using Terraform. This evidence proves you can build resilient, production-grade systems that minimize manual intervention and technical debt.
Mentioning orchestration tools such as Airflow or Dagster confirms your ability to manage complex workflow dependencies at scale. The shift toward MLOps and real-time streaming requires familiarity with Kafka or Flink. As companies move away from batch processing, showing you can deploy predictive models into production is highly valuable.
Highlighting these advanced skills suggests you are prepared for the future of automated, intelligent data platforms.
Navigating International Credentials and US Resume Standards
Retain the original title of your international degree while researching how to present your educational background to US employers. If you earned a degree from INSA Lyon or another French institution, list the original name to maintain academic integrity. You should check with the competent authority or employer requirements regarding credential evaluation services for migration purposes.
This approach ensures your educational history is accurately represented without making unauthorized claims of equivalence.
Adhere strictly to US formatting norms by excluding all personal demographic information. Never include a photo, age, gender, or marital status, as these details can trigger legal compliance issues for American employers. Focus entirely on your professional trajectory and technical contributions rather than personal background.
Ensure your document uses American English spelling and standard US letter sizing rather than A4.
Emphasize project outcomes and technical certifications over institutional prestige if your school is not globally recognized. The American tech sector is largely meritocratic and prioritizes your GitHub portfolio and work history. Professional summaries should focus on your years of experience and core tech stack.
Always verify if specific state-level licenses are required if your work intersects with regulated industries, though this is rare for pure data engineering roles.
Strategic Tailoring and Common Pitfalls to Avoid
Avoid the common mistake of creating a generic skill cloud that lists every tool you have ever used. This lack of focus makes it difficult for a recruiter to determine your actual area of expertise. Instead, group your skills into logical categories such as Languages, Orchestration, and Cloud Infrastructure.
This organization makes your resume skimmable and highlights your primary strengths within seconds.
Ensure your professional summary acts as a high-impact elevator pitch rather than a list of demands. A strong summary highlights your years of experience and your most significant architectural achievement. Avoid vague objectives like seeking a challenging role and instead focus on what you offer the employer.
This section sets the tone for the rest of the document and should be updated for every application.
Do not neglect the importance of technical documentation and collaborative soft skills. Mentioning that you authored Confluence guides or led a team of four engineers shows you can scale your impact through others. Many candidates fail by focusing solely on code while ignoring the communication required for large-scale migrations.
Finally, double-check that all links to your LinkedIn or portfolio are active and lead to professional, updated profiles.
| Vague Description | Concrete Achievement |
|---|---|
| Worked with Spark and Python for data processing. | Optimized PySpark jobs to reduce processing time by 50% for 2TB datasets. |
| Responsible for cloud migration. | Led migration of 50+ pipelines from on-premise to AWS, saving $20k monthly. |
| Improved data quality. | Implemented Great Expectations to reduce data entry errors by 30%. |
Frequently asked questions
Should I prioritize Python or SQL on my resume?
Both are essential. SQL is the language of data manipulation, while Python is the language of automation and engineering. List both prominently, as they are the most common requirements in job descriptions.
Which certifications are best for Data Engineers in 2026?
Cloud-specific certifications like AWS Certified Data Engineer or Google Professional Data Engineer are highly valued. Platform-specific credentials like Snowflake SnowPro or Databricks Associate also carry significant weight.
How long should a Senior Data Engineer resume be?
Aim for two pages if you have over 5 years of experience. This allows enough space to detail technical projects and quantifiable impacts without overwhelming the reader.